🧙♂️ CoherentEdit: Unified Multimodal Understanding and Implicit Lighting Conditioned Diffusion for Controllable Video Editing
Abstract
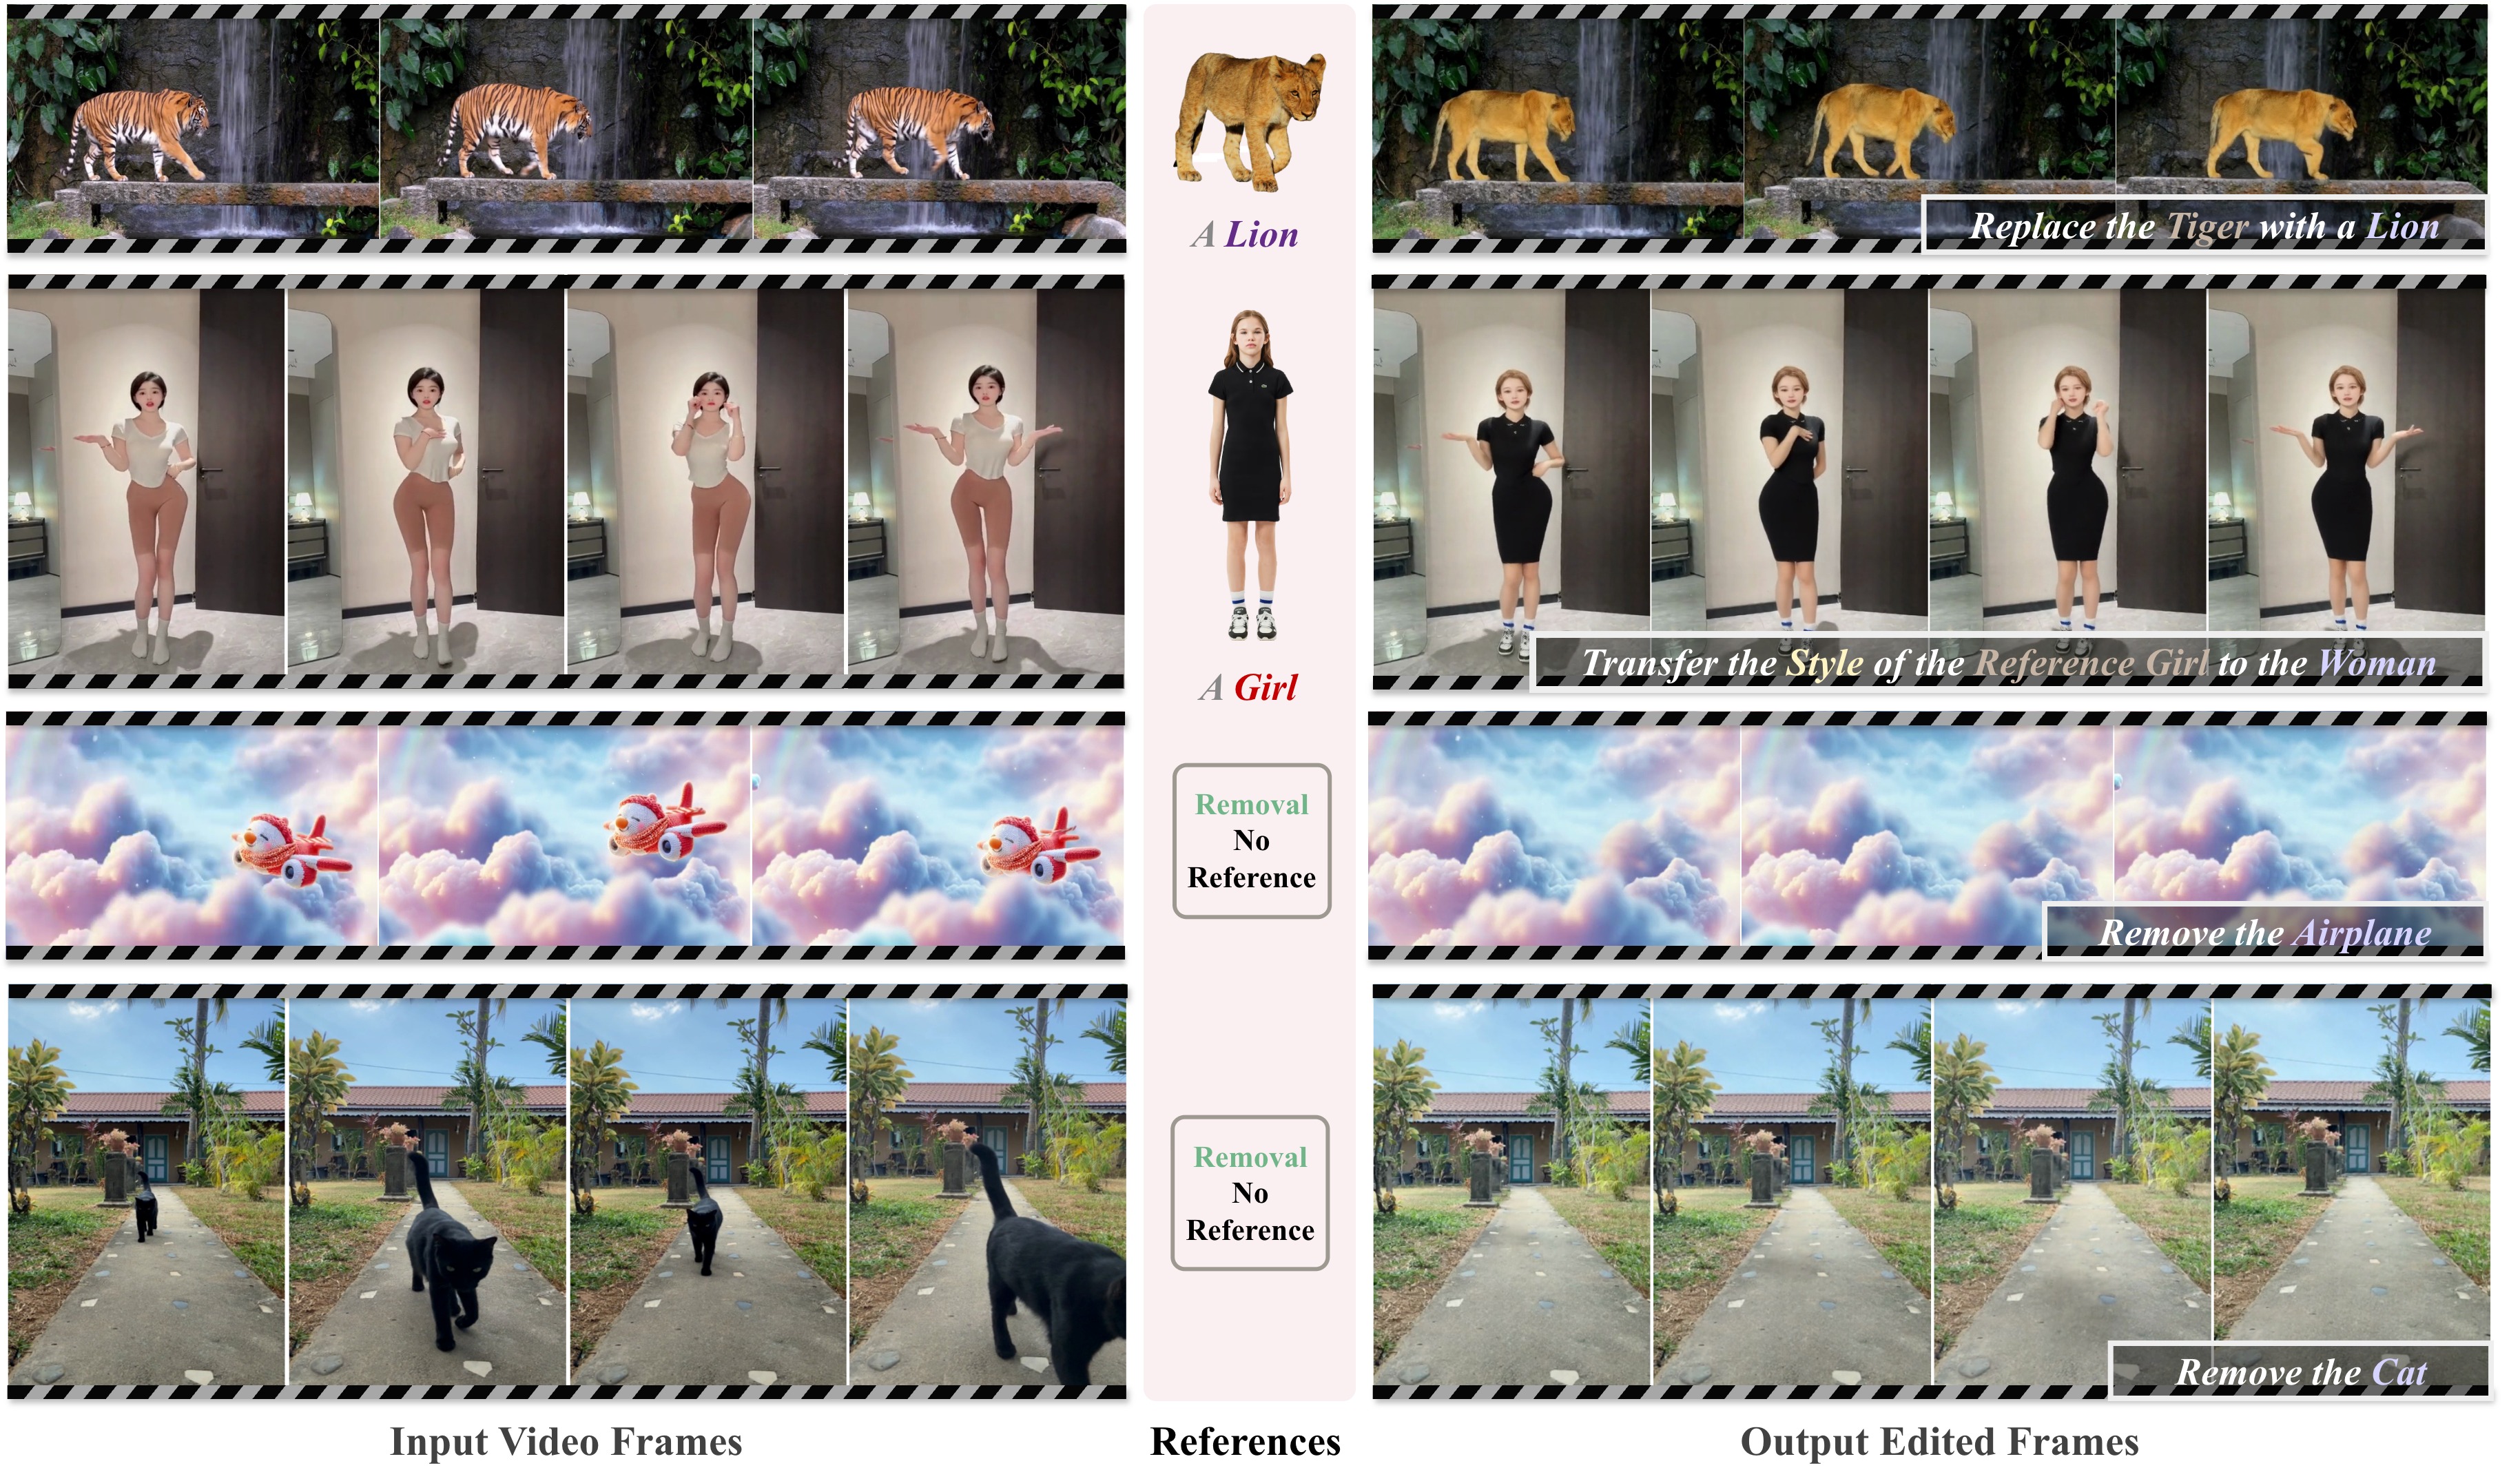
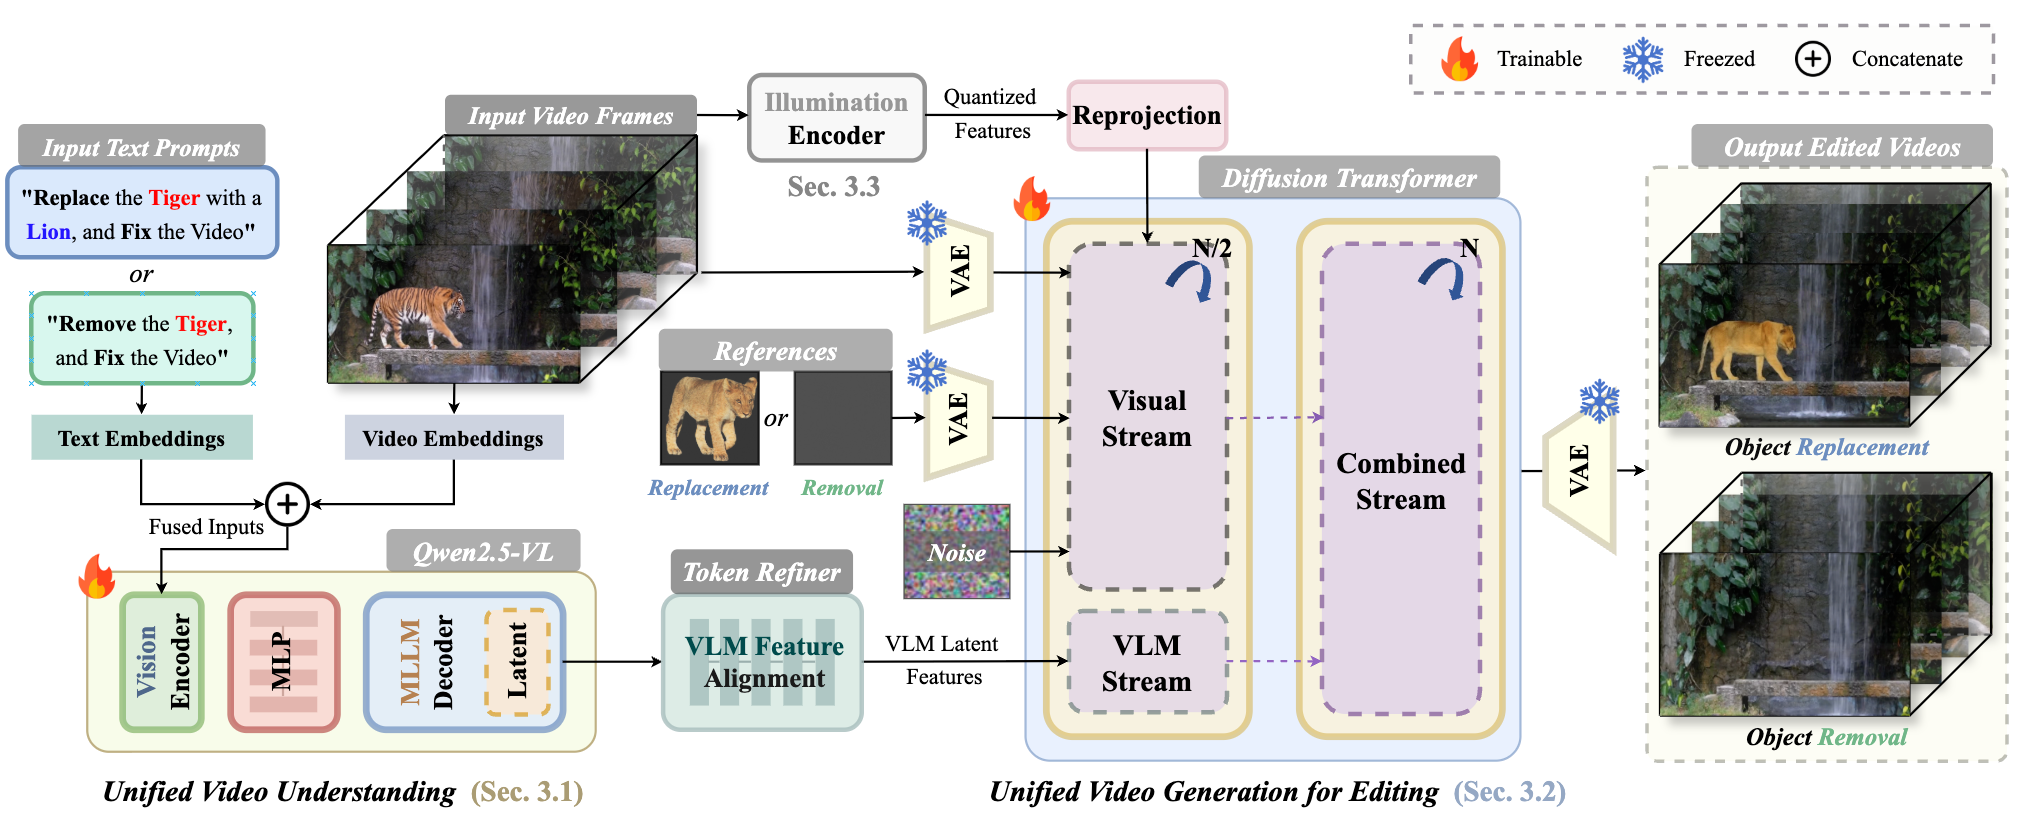
Recent progress in video generation has intensified demand for controllable video editing. Vision-language models have demonstrated strong capabilities in video understanding, yet they appear to offer limited support for video generation and editing.We present CoherentEdit, a two-stage framework for unified multimodal understanding and video editing. We explore how to leverage the powerful video understanding capabilities of Vision-Language Models (VLMs) to better serve video generation and editing.In the first stage, the VLM model interprets the user instruction and the source video to derive unified multimodal embedding and we explored how to push the VLM output from text space to multimodal space.In the second stage, a diffusion-based generation network performs controllable video synthesis. To better preserve lighting coherence, CoherentEdit extracts a implicit lighting representation from the source video via a VQ‑VAE encoder, and injects this representation into the generation process to promote consistent illumination and shadowing across edited regions and unchanged context. Experiments demonstrate that our method outperforms the state-of-the-art approaches.
Overview
Visualization Results
Different types of Human Animation
|
|
|||||
|---|---|---|---|---|---|
Different types of Video Editing
|
|
|
|
|---|---|---|---|
Various Scenes For Object Erasement
Human Editing Comparison
| Reference Video | Ref Image | vace | HunyuanCus | Omni-Video | Rf-Editor | Ours |
|---|---|---|---|---|---|---|
|
|
||||||
|
|
Animal Editing Comparison
| Reference Video | Propainter | HunyuanCus | DiffuEraser | Ours |
|---|---|---|---|---|